
On this page
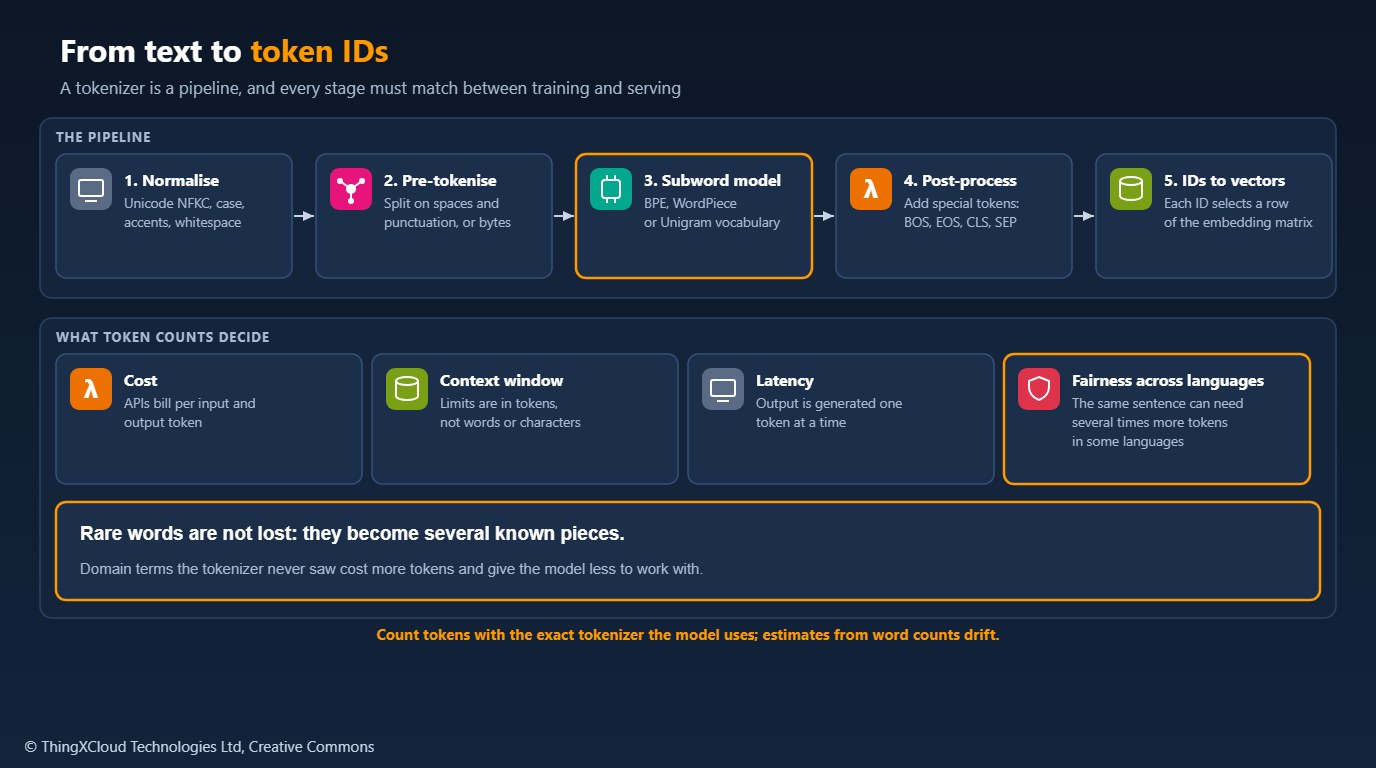
Every large language model reads and writes tokens, not words. The tokenizer decides how text becomes those tokens, and with them how much a request costs, how much fits in the context window, and how well the model handles words it rarely saw in training. It is also the part of an LLM system most often treated as a black box until a bill, a truncated prompt or a garbled name in another language forces someone to look.
This article explains the three subword algorithms in common use as of April 2024 (byte pair encoding, WordPiece and Unigram), the pipeline around them, and the production problems that come from tokenization rather than from the model. The sample code contains a short BPE implementation to read, and a script that trains all three on your own text and compares them.
Why subwords
Splitting on words gives a vocabulary that never ends: every name, product code and inflection is a new entry, and anything unseen becomes an unknown token. Splitting into characters fixes that but makes sequences several times longer, and the model has to learn spelling before it can learn meaning. Subword tokenizers sit between the two. Frequent words become single tokens; rare words are built from smaller pieces the vocabulary already has, so nothing is unrepresentable and common text stays short.
The three algorithms
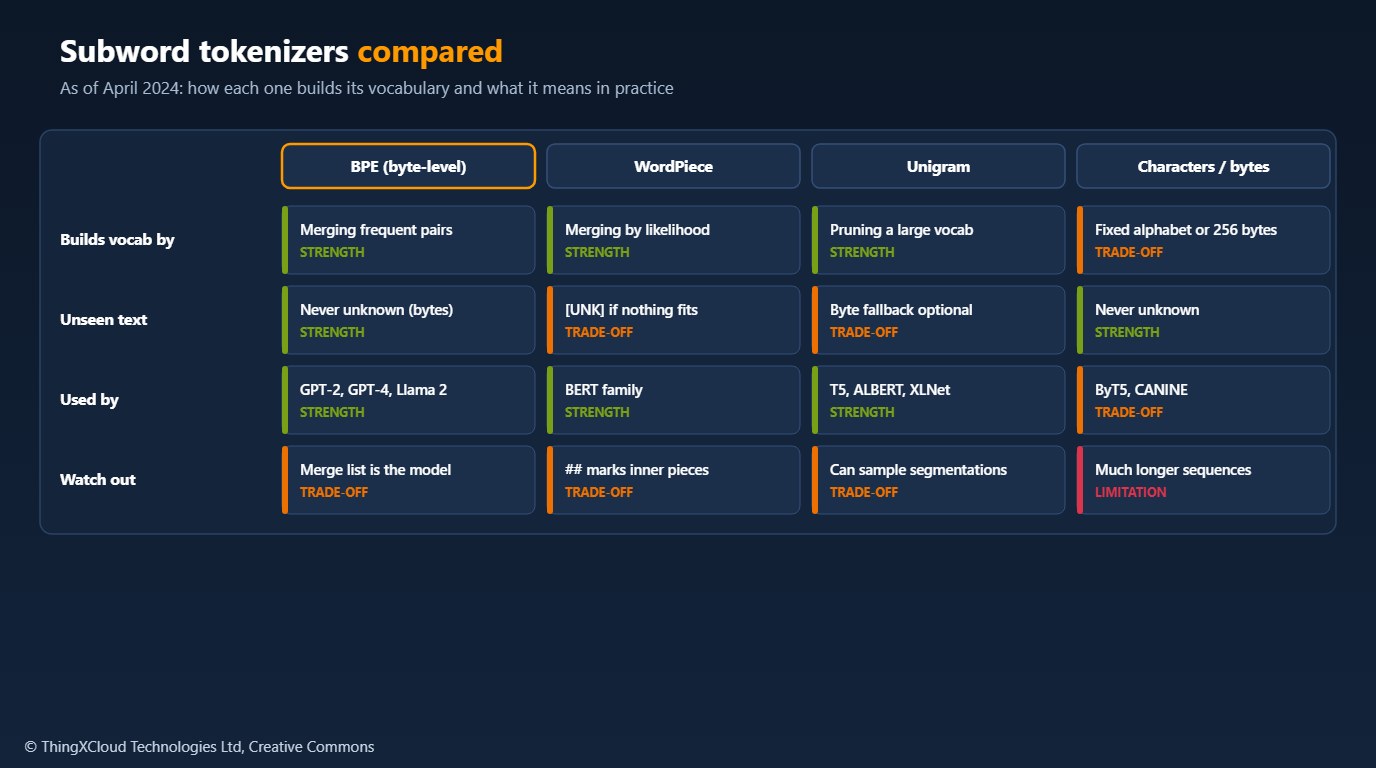
Byte pair encoding was adapted from a compression algorithm for neural machine translation by Sennrich, Haddow and Birch (2016). Training starts from characters and repeatedly merges the most frequent adjacent pair; the ordered list of merges is the tokenizer. GPT-2 introduced byte-level BPE, which starts from the 256 byte values instead of characters, so any input, in any script, can be encoded without an unknown token. OpenAI’s GPT-3.5 and GPT-4 models use a byte-level BPE vocabulary of about 100,000 tokens (cl100k_base in the tiktoken library), and Meta’s Llama 2 uses a 32,000-token BPE model built with SentencePiece.
WordPiece, used by BERT and its descendants, also builds its vocabulary by merging, but chooses the merge that most increases the likelihood of the training data rather than the most frequent pair. Pieces that continue a word carry a ## prefix, and a word that cannot be built from the vocabulary becomes [UNK].
Unigram works the other way round: it starts from a large candidate vocabulary and removes the pieces whose loss least affects the likelihood of the corpus, until it reaches the target size. Because it is a probabilistic model it can produce several segmentations of the same word, which some training setups use as regularisation. T5, ALBERT and XLNet use Unigram models built with SentencePiece, a library that treats whitespace as an ordinary symbol so it can train directly on raw text in any language.
A short BPE implementation
The quickest way to understand BPE is to read one. This version counts adjacent symbol pairs across a word-frequency table, merges the most frequent, and repeats. On the four-word example from the original paper (low, lower, newest, widest) it learns e s, then es t, then est </w>, which is why an unseen word such as lowest comes out as low plus est</w>.
"""Byte Pair Encoding in about 60 lines, for reading rather than production.

Training starts from characters and repeatedly merges the most frequent
adjacent pair across the corpus. Encoding replays the learned merges in the
order they were learned. Words end with "</w>" so that a suffix such as
"est</w>" is a different token from "est" inside a word, as in Sennrich et
al. (2016). Production tokenizers (GPT-2 style byte-level BPE, the Hugging
Face `tokenizers` library) work on bytes and are far faster, but follow the
same idea.
"""
from __future__ import annotations

from collections import Counter

EOW = "</w>"


def _words(corpus: dict[str, int]) -> dict[tuple[str, ...], int]:
    return {tuple(w) + (EOW,): n for w, n in corpus.items()}


def _pair_counts(vocab: dict[tuple[str, ...], int]) -> Counter:
    pairs: Counter = Counter()
    for symbols, n in vocab.items():
        for a, b in zip(symbols, symbols[1:]):
            pairs[(a, b)] += n
    return pairs


def _merge(vocab: dict[tuple[str, ...], int], pair: tuple[str, str]) -> dict[tuple[str, ...], int]:
    merged = {}
    for symbols, n in vocab.items():
        out, i = [], 0
        while i < len(symbols):
            if i + 1 < len(symbols) and (symbols[i], symbols[i + 1]) == pair:
                out.append(symbols[i] + symbols[i + 1])
                i += 2
            else:
                out.append(symbols[i])
                i += 1
        merged[tuple(out)] = merged.get(tuple(out), 0) + n
    return merged


def train(corpus: dict[str, int], num_merges: int) -> list[tuple[str, str]]:
    """Learn up to `num_merges` merges from word frequencies.

    Ties go to the alphabetically smallest pair, so training is deterministic.
    """
    vocab = _words(corpus)
    merges: list[tuple[str, str]] = []
    for _ in range(num_merges):
        pairs = _pair_counts(vocab)
        if not pairs:
            break
        best = min(pairs.items(), key=lambda kv: (-kv[1], kv[0]))[0]
        if pairs[best] < 2:
            break                       # merging a pair seen once teaches nothing
        vocab = _merge(vocab, best)
        merges.append(best)
    return merges


def encode_word(word: str, merges: list[tuple[str, str]]) -> list[str]:
    symbols = list(word) + [EOW]
    for pair in merges:
        i, out = 0, []
        while i < len(symbols):
            if i + 1 < len(symbols) and (symbols[i], symbols[i + 1]) == pair:
                out.append(symbols[i] + symbols[i + 1])
                i += 2
            else:
                out.append(symbols[i])
                i += 1
        symbols = out
    return symbols


def encode(text: str, merges: list[tuple[str, str]]) -> list[str]:
    return [tok for word in text.split() for tok in encode_word(word, merges)]
%%{init: {'theme': 'base', 'themeVariables': {'primaryColor': '#FFF3E0', 'primaryTextColor': '#232F3E', 'primaryBorderColor': '#FF9900', 'lineColor': '#232F3E', 'clusterBkg': '#F8FAFC', 'clusterBorder': '#CBD5E1', 'edgeLabelBackground': '#FFFFFF', 'nodeTextColor': '#232F3E'}}}%%
flowchart TD
A["Split every word<br/>into characters"] --> B["Count adjacent pairs,<br/>weighted by word frequency"]
B --> C{"Vocabulary full or<br/>no pair seen twice?"}
C -- "No" --> D["Merge the most<br/>frequent pair everywhere"]
D --> E["Append the merge<br/>to the merge list"]
E --> B
C -- "Yes" --> F["Merge list and vocabulary<br/>are the tokenizer"]
classDef aws fill:#FFF3E0,stroke:#FF9900,stroke-width:2px,color:#232F3E
classDef ok fill:#F0FFF4,stroke:#1D8102,stroke-width:2px,color:#145202
class A,B,C,D,E aws
class F okCompare them on your own text
Which algorithm is “best” matters less than the corpus the tokenizer was trained on. A tokenizer trained on general web text will split clinical, legal or product vocabulary into many small pieces. The second script trains BPE, WordPiece and Unigram with the Hugging Face tokenizers library on a corpus you provide, with the same vocabulary size, and reports tokens per word and the unknown-token rate for test sentences:
"""Train BPE, WordPiece and Unigram tokenizers on the same corpus and compare them.

Uses the Hugging Face `tokenizers` library, so nothing is downloaded: the
tokenizers are trained locally from your own text. The report shows how many
tokens each one needs per word for each test text, which is what drives
context-window use and per-token cost.

Usage:
    python compare.py corpus.txt --vocab 8000 --text "Some English text" --text "Ein deutscher Text"
"""
from __future__ import annotations

import argparse
import unicodedata

from tokenizers import Tokenizer, models, normalizers, pre_tokenizers, trainers

SPECIALS = ["[UNK]", "[PAD]", "[BOS]", "[EOS]"]


def build(kind: str, vocab_size: int, normalize: bool = True) -> tuple[Tokenizer, object]:
    if kind == "bpe":
        tok = Tokenizer(models.BPE(unk_token="[UNK]"))
        trainer = trainers.BpeTrainer(vocab_size=vocab_size, special_tokens=SPECIALS, min_frequency=2)
    elif kind == "wordpiece":
        tok = Tokenizer(models.WordPiece(unk_token="[UNK]"))
        trainer = trainers.WordPieceTrainer(vocab_size=vocab_size, special_tokens=SPECIALS, min_frequency=2)
    elif kind == "unigram":
        tok = Tokenizer(models.Unigram())
        trainer = trainers.UnigramTrainer(vocab_size=vocab_size, special_tokens=SPECIALS, unk_token="[UNK]")
    else:
        raise ValueError(f"unknown tokenizer kind: {kind}")
    if normalize:
        # NFKC folds visually identical forms (composed/decomposed accents,
        # full-width letters) into one, so they tokenize the same way.
        tok.normalizer = normalizers.NFKC()
    tok.pre_tokenizer = pre_tokenizers.Whitespace()
    return tok, trainer


def train_all(lines: list[str], vocab_size: int, normalize: bool = True) -> dict[str, Tokenizer]:
    out = {}
    for kind in ("bpe", "wordpiece", "unigram"):
        tok, trainer = build(kind, vocab_size, normalize)
        tok.train_from_iterator(lines, trainer=trainer)
        out[kind] = tok
    return out


def tokens_per_word(tok: Tokenizer, text: str) -> float:
    words = len(text.split())
    return len(tok.encode(text).tokens) / words if words else 0.0


def unknown_rate(tok: Tokenizer, text: str) -> float:
    toks = tok.encode(text).tokens
    return toks.count("[UNK]") / len(toks) if toks else 0.0


def main() -> None:
    ap = argparse.ArgumentParser(description=__doc__.splitlines()[0])
    ap.add_argument("corpus")
    ap.add_argument("--vocab", type=int, default=8000)
    ap.add_argument("--text", action="append", required=True)
    args = ap.parse_args()
    with open(args.corpus, encoding="utf-8") as fh:
        lines = [unicodedata.normalize("NFC", l) for l in fh if l.strip()]
    toks = train_all(lines, args.vocab)
    for text in args.text:
        print(text[:60])
        for kind, tok in toks.items():
            print(f"  {kind:<10} tokens/word={tokens_per_word(tok, text):.2f} "
                  f"unknown={unknown_rate(tok, text):.1%} {tok.encode(text).tokens[:12]}")


if __name__ == "__main__":
    main()
For a pre-trained model you cannot change the tokenizer, but you can measure it: count tokens for a sample of real prompts with the model’s own tokenizer, per language and per document type, and use that ratio for capacity and cost planning instead of a rule of thumb about words per token.
Where tokenization goes wrong in production
- Mismatched tokenizers. Serving a fine-tuned model with the base model’s tokenizer, or a different version of it, silently changes the token IDs. Ship the tokenizer files with the model weights and load both from the same artefact.
- Unicode normalisation. “é” can be one code point or two (an e plus a combining accent). Without normalisation the two forms tokenize differently; the sample’s tests show both cases. Normalise input the same way the tokenizer did in training.
- Special tokens in user input. If user text containing a string such as
<|endoftext|>is encoded as the special token rather than as plain text, a user can end a turn or inject structure. Encode user input with special-token parsing disabled. - Truncation. Limits are in tokens. Truncating by characters can cut a multi-byte character or exceed the limit anyway; truncate on token boundaries and keep the instructions you cannot lose at the start.
- Uneven cost across languages. Text in languages under-represented in the tokenizer’s training data can need several times more tokens for the same meaning, which raises cost and shortens the effective context for those users.
Token-per-word rules of thumb are averages for English prose. Code, tables, identifiers, non-Latin scripts and domain vocabulary differ widely. Budget context windows and costs from token counts measured with the exact tokenizer of the model you call.
Tokenization is reversible: token IDs are a different encoding of the same text, not anonymisation. Treat stored prompts, token logs and cached embeddings with the same controls as the original text.
The sample was tested with Python 3.13, tokenizers==0.15.2 and pytest==8.1.1: nine tests cover the merge order on the Sennrich et al. example, encoding of unseen words, deterministic training of all three algorithms, in-domain versus out-of-domain token counts, NFKC normalisation of composed and decomposed accents, and reserved special-token IDs. Vocabulary sizes and model associations are from the cited papers and the models’ published tokenizers.
Key takeaways
- Subword tokenizers keep common words whole and build rare ones from pieces, so nothing is unrepresentable.
- BPE merges frequent pairs, WordPiece merges by likelihood, Unigram prunes a large vocabulary; byte-level BPE never produces unknown tokens.
- The training corpus matters more than the algorithm: domain terms and some languages cost more tokens.
- Ship the tokenizer with the model, normalise input consistently, and never parse special tokens in user text.
- Plan cost and context with token counts from the exact tokenizer, not word-based estimates.
Have you been surprised by a token count, or by how a tokenizer split your domain’s vocabulary? Share the example in the comments.
The complete sample for this article is on GitHub: nithinmohantk/blog-samples-working-repo/subword-tokenizers. Clone it with git clone https://github.com/nithinmohantk/blog-samples-working-repo.git and open the subword-tokenizers folder. Its README says how to run it and what has been verified.
Glossary
- Token
- The unit a language model reads and writes; usually a word, part of a word or a byte sequence.
- BPE
- Byte pair encoding: builds a vocabulary by repeatedly merging the most frequent adjacent pair.
- Byte-level BPE
- BPE that starts from the 256 byte values, so any text can be encoded.
- WordPiece
- A merge-based tokenizer that chooses merges by likelihood gain; used by BERT.
- Unigram
- A tokenizer that prunes a large candidate vocabulary using a unigram language model.
- SentencePiece
- A library that trains BPE or Unigram tokenizers directly on raw text, treating spaces as symbols.
- NFKC
- A Unicode normalisation form that folds equivalent characters into one representation.
References & Further Reading
- → Neural Machine Translation of Rare Words with Subword Units— Sennrich, Haddow and Birch: BPE for subwords
- → SentencePiece— Kudo and Richardson: language-independent subword tokenizer
- → Sample code for this article— Minimal BPE and a BPE/WordPiece/Unigram comparison
Discover more from C4: Container, Code, Cloud & Context
Subscribe to get the latest posts sent to your email.
