GPT-5.2-Codex is OpenAI’s coding model for long, agentic work: large refactors, migrations and feature builds carried across many steps. OpenAI released it in its Codex products on 18 December 2025. On 14 January 2026 it reached the OpenAI API, became generally available through Azure OpenAI in Microsoft Foundry, and became generally available in GitHub Copilot. On 26 January Copilot extended it to Visual Studio, JetBrains IDEs, Xcode and Eclipse.
Three properties get most of the attention: a 400,000-token context window, image input, and availability inside the Azure boundary. This article sets out what OpenAI, Microsoft and GitHub have published about each, with the source beside every figure, and then works through the question an architect has to answer before approving it for a team: how much of a repository fits in that window, what a working session costs, and what the prompt has to look like for the cost to stay down.
Facts about the model come from the vendors’ own pages, linked where they are used. Where a commonly repeated figure has no vendor source, the article says so. The code is a cost model and a client for the Responses API. It was tested with the official openai package against a local stand-in that applies the documented caching rules. No request was sent to the model, and nothing here measures the quality of its answers.
What has been published
| Property | Value | Source |
|---|---|---|
| Context window | 400,000 tokens | OpenAI model page, Microsoft Foundry announcement |
| Maximum output | 128,000 tokens | OpenAI model page |
| Knowledge cutoff | 31 August 2025 | OpenAI model page |
| Input and output | Text and images in, text out | OpenAI model page |
| Reasoning effort | low, medium, high, xhigh | OpenAI model page |
| API | Responses API; streaming, function calling and structured outputs supported; fine-tuning not supported | OpenAI model page |
| Price per million tokens | Input $1.75, cached input $0.175, output $14.00 | OpenAI model page, Microsoft Foundry announcement |
| Benchmarks | OpenAI states state-of-the-art results on SWE-Bench Pro and Terminal-Bench 2.0 | OpenAI announcement |
| Long sessions | Native context compaction, better tool calling, improved behaviour on Windows | OpenAI announcement |
| Vision | Stronger reading of screenshots, technical diagrams, charts and UI surfaces | OpenAI announcement |
| Languages | “50+” languages, among them Python, JavaScript and TypeScript, C#, Java, Go and Rust | Microsoft Foundry announcement |
| GitHub Copilot | Enterprise, Business, Pro and Pro+; an administrator must enable the model for Business and Enterprise | GitHub changelog, 14 January, 26 January |
Some figures that circulate with this model have no source in any of those pages. Neither OpenAI nor Microsoft publishes a HumanEval score for it, a first-token latency, or a tiered list of supported languages, and the benchmark claims on OpenAI’s page are for SWE-Bench Pro and Terminal-Bench 2.0. There is no documented request flag that turns caching on; prompt caching is automatic and depends on how the prompt is built, which is the subject of the second half of this article. If a number matters to a decision, measure it on your own code.
Architecture: three ways to consume the model
The same model is reached through three different products, and they differ in who controls the prompt, where the data goes and how it is paid for.
%%{init: {'theme':'base','themeVariables':{'primaryColor':'#FFF3E0','primaryTextColor':'#232F3E','primaryBorderColor':'#FF9900','lineColor':'#232F3E','clusterBkg':'#F8FAFC','clusterBorder':'#CBD5E1','edgeLabelBackground':'#FFFFFF','nodeTextColor':'#232F3E'}}}%%
flowchart TD
    D["Developer or pipeline"] --> C["Codex CLI, IDE extension or cloud
with a ChatGPT plan"]
    D --> H["GitHub Copilot
model picker"]
    D --> A["Your own code or agent
through the Responses API"]
    A --> O["api.openai.com"]
    A --> F["Azure OpenAI in
Microsoft Foundry"]
    C -. "can be pointed at" .-> F
    style A fill:#FFF3E0,stroke:#FF9900,stroke-width:2px,color:#232F3E
    style F fill:#EBF8FF,stroke:#0073BB,stroke-width:2px,color:#004C74
    style O fill:#F0FFF4,stroke:#1D8102,stroke-width:2px,color:#145202
style H fill:#F3E8FF,stroke:#7C3AED,stroke-width:2px,color:#4C1D95| Route | Advantages | Disadvantages and risks | Cost and operations |
|---|---|---|---|
| Codex products | The harness OpenAI tunes the model for: compaction, sandboxing, tool use | The prompt and context are managed for you. Data handling follows the ChatGPT plan | Per-seat plan with usage limits |
| GitHub Copilot | Already in the IDE. Policy is set per organisation | Context selection is Copilot’s. No control over prompt layout or caching | Per-seat plan and premium requests |
| Responses API on api.openai.com | Full control of prompt, tools and reasoning effort | You build the harness. Data leaves for OpenAI under your API terms | Per token, as in the table above |
| Responses API through Microsoft Foundry | Same control, inside your Azure tenant: Entra ID, private networking, Azure Policy, one bill | Deployment types and regions differ; check where processing happens for the one you choose | Per token at the same list prices |
For interactive work the first two routes are the practical ones. The API routes matter when the model is a component: a review bot in a pipeline, a migration tool, an internal agent. That is where prompt layout and cost become the architect’s problem, and the rest of this article is about them.
How much code is 400,000 tokens?
Microsoft’s announcement puts the window at about 100,000 lines of code. That depends heavily on the code. To get a figure from real files, the sample counts a repository of C#, Python and Terraform with tiktoken and the o200k_base encoding, which is the one tiktoken selects for the GPT-5 family.
def count_repository(root: pathlib.Path, suffixes: tuple[str, ...], encoder) -> RepositoryCount:
    """Counts every source file under root with one of the suffixes, in path order, skipping anything that is not UTF-8."""
    files = lines = tokens = 0
    skipped = {"node_modules", "bin", "obj", "out", "site-packages"}
    for path in sorted(p for p in root.rglob("*") if p.is_file() and p.suffix in suffixes):
        if any(part.startswith(".") or part in skipped for part in path.relative_to(root).parts[:-1]):
            continue   # version control, virtual environments, build output and installed packages are not the repository
        try:
            text = path.read_text(encoding="utf-8")
        except UnicodeDecodeError:
            continue
        files += 1
        lines += text.count("\n") + (0 if text.endswith("\n") or not text else 1)
        tokens += len(encoder.encode(text))
    return RepositoryCount(files, lines, tokens)
== 1. How much code is 400,000 tokens?
language files lines tokens tokens per line lines in 400,000 tokens
C# 124 10,462 132,069 12.6 31,686
Python 97 7,374 99,145 13.4 29,750
Terraform 89 3,013 21,641 7.2 55,691
all four 310 20,849 252,855 12.1 32,982About twelve tokens a line for application code, so 400,000 tokens is nearer 33,000 lines of C# or Python than 100,000. Terraform, with its short lines, is denser. A repository of a few hundred files fits. A typical enterprise service with its tests does not, and the window also has to hold everything else in the request.
One practical point came out of the count. A source file that contains the literal text of a special token, as a tokenizer’s own tests do, makes tiktoken raise an error unless it is told to treat the file as ordinary text. Code is data here, and the counter has to say so.
class PlainText:
    """Wraps a tiktoken encoding so that source code is always counted as ordinary text. Without this, a file
    that happens to contain the characters of a special token, such as a tokenizer test, stops the count."""

    def __init__(self, encoding):
        self._encoding = encoding

    def encode(self, text: str) -> list[int]:
        return self._encoding.encode(text, disallowed_special=())
The window is a budget
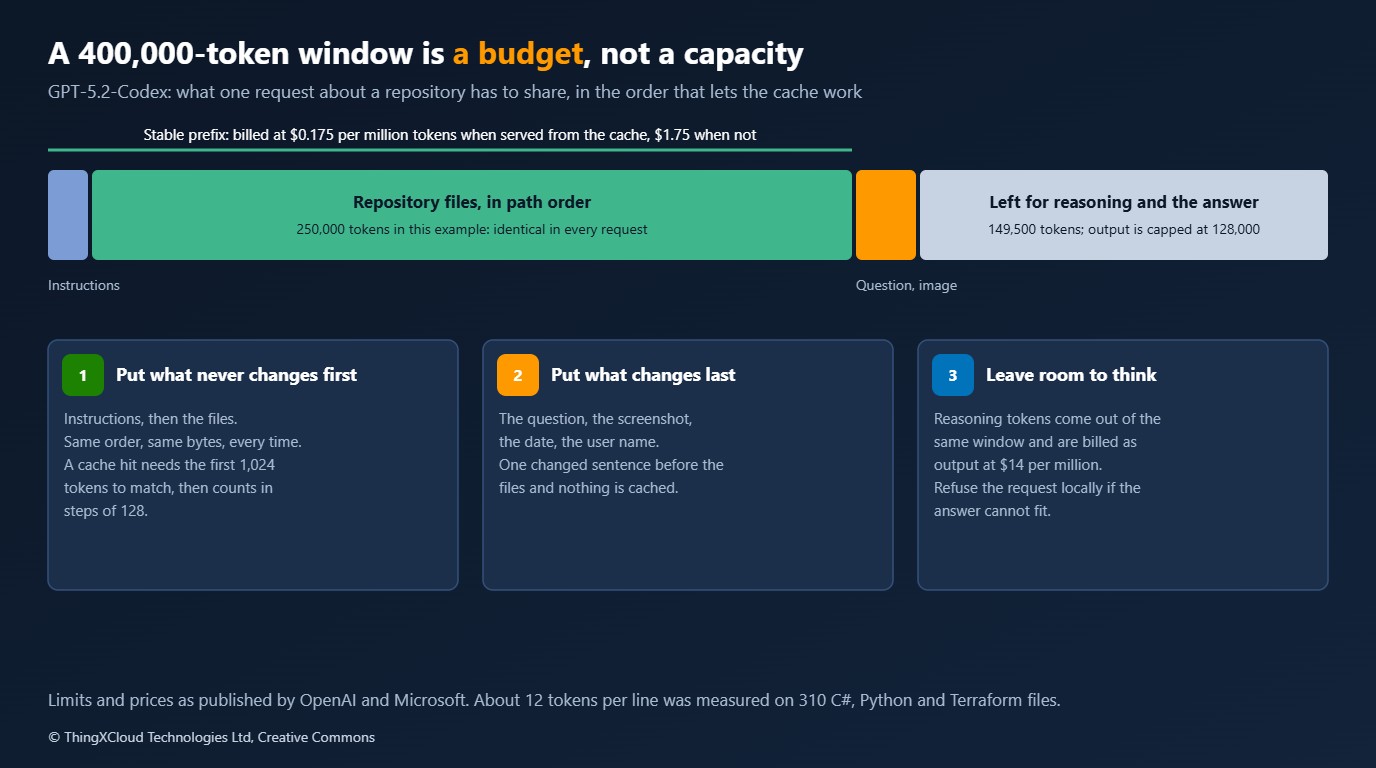
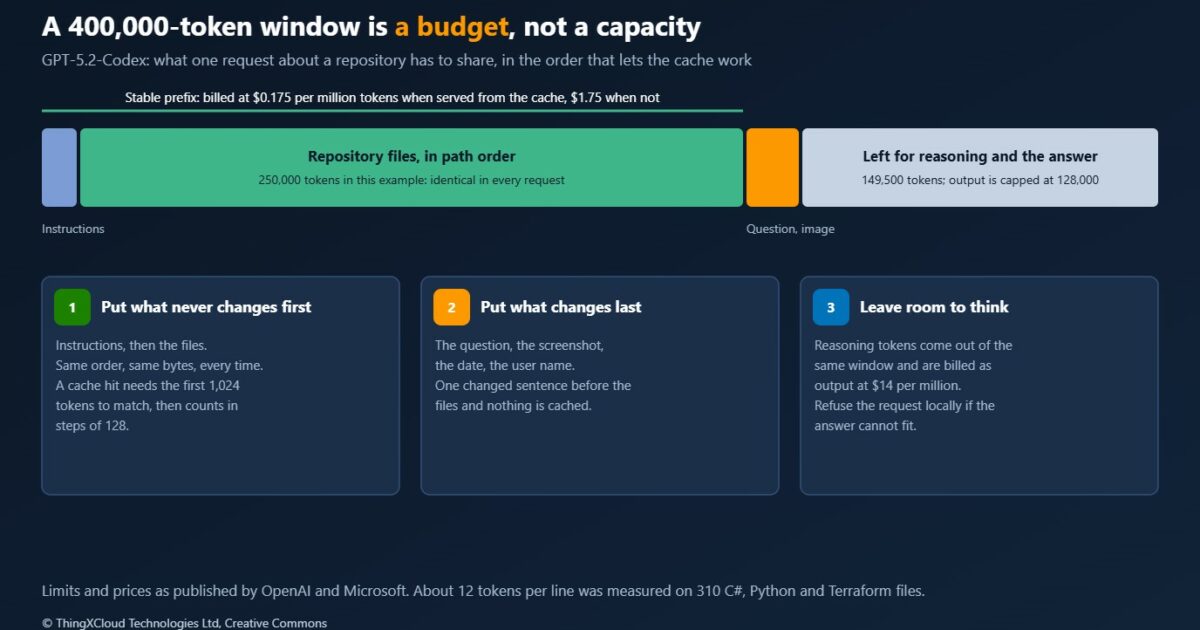
The window is shared between what is sent and what comes back. Reasoning tokens, which the model spends before it answers, come out of the same window and are billed as output. A request that fills the window with files leaves no room to think. The client therefore checks, before it sends anything, that enough is left.
def room_for_output(prices: Prices, prefix_tokens: int, question_tokens: int) -> int:
    """Tokens left in the window for reasoning and the answer. Negative means the request does not fit."""
    return prices.context_window - prefix_tokens - question_tokens
left = room_for_output(self._prices, self.prefix_tokens, len(self._encoder.encode(question)))
if left < self._max_output:
raise DoesNotFit(f"{self.prefix_tokens:,} tokens of repository leave {left:,} for the answer; {self._max_output:,} are needed.")The alternative to fitting everything in is the one OpenAI built into its own Codex harness: let the agent read files as it needs them and compact the conversation as it grows. For a tool that asks many questions about a repository small enough to fit, sending the files in full is simpler and, as the next section shows, can be cheap.
Prompt caching is automatic; prompt order is yours
Cached input costs $0.175 per million tokens against $1.75, a tenth. OpenAI and Microsoft document the same rules for when a request is served from the cache.
| Rule | Consequence |
|---|---|
| Caching is on by default; there is no flag to set | Nothing to enable, and nothing to forget |
| A prompt must be at least 1,024 tokens | Small prompts are never cached |
| The match is on the prefix: the beginning of the prompt must be identical to an earlier one | Anything that varies has to come after everything that does not |
| Beyond 1,024 tokens, the cached part is counted in steps of 128 | The last few tokens of the prefix may be billed at the full rate |
| An entry is kept for a few minutes of inactivity, and no longer than an hour | A burst of questions benefits; one question an hour does not |
| Caches are not shared between organisations, or between Azure subscriptions | No cross-tenant exposure, and no benefit from another team’s traffic |
The response reports usage.input_tokens_details.cached_tokens | You can, and should, measure the hit rate |
The design consequence is a prompt with a fixed order: instructions, then the repository rendered the same way every time, then the question. The session object renders the files once, in path order, and derives a cache key from their content so that requests about the same snapshot are routed to the same cache.
        # Files in path order with a fixed header each: the same repository always renders to the same text.
        self._repository = "\n".join(f"### FILE {path}\n{files[path]}" for path in sorted(files))
        self.prefix_tokens = len(encoder.encode(INSTRUCTIONS)) + len(encoder.encode(self._repository))
        # One key per repository snapshot keeps requests that share this prefix on the same cache.
        self._cache_key = "repo-" + hashlib.sha256(self._repository.encode("utf-8")).hexdigest()[:24]
response = self._client.responses.create(
model=self._model,
instructions=INSTRUCTIONS,
input=[
{"role": "user", "content": [{"type": "input_text", "text": self._repository}]},
{"role": "user", "content": last},
],
reasoning={"effort": self._effort},
max_output_tokens=self._max_output,
prompt_cache_key=self._cache_key,
store=False, # do not keep the repository in stored responses
)The cache key is an OpenAI request parameter. On Microsoft Foundry, check the prompt caching documentation for whether your deployment uses it; the prefix rule applies either way.
The response’s usage block is turned into a cost with the published prices, so every answer comes back with what it cost and how much of it was cached.
    def cost(self, input_tokens: int, cached_tokens: int, output_tokens: int) -> float:
        """Dollars for one request. Output tokens include the reasoning tokens, which are billed as output."""
        fresh = input_tokens - cached_tokens
        return (fresh * self.input + cached_tokens * self.cached_input + output_tokens * self.output) / 1_000_000
To test the client without an account, the sample includes a local server that accepts POST /v1/responses, returns the documented response shape, and applies the rules in the table to the prompts it receives. The official openai package talks to it as it would to the service.
    def _cached(self, key: str, tokens: list[int]) -> int:
        best = 0
        for earlier in self.seen.get(key, []):
            shared = 0
            for a, b in zip(earlier, tokens):
                if a != b:
                    break
                shared += 1
            best = max(best, shared)
        if best < CACHE_MINIMUM:
            return 0
        return best - (best - CACHE_MINIMUM) % CACHE_STEP
== 3. The client against the local stand-in
8 C# files, 23,327 tokens of instructions and repository
ok the first request is retried after a 429 and then answered
ok nothing is cached on the first request
ok a different question about the same repository is served 23,296 cached tokens: the whole prefix, to the nearest step of 128
ok the second request costs less than a quarter of the first
first request 23,336 input, 0 cached, $0.0467
second request 23,337 input, 23,296 cached, $0.0100
ok the request puts the repository before the question, sets a cache key and does not store the response
ok an image is sent after the question as a data URL, and the repository is still served from the cache
ok one changed sentence in front of the repository and nothing is cached
ok a new snapshot of the repository has its own cache key and starts cold
refused locally: 390,041 tokens of repository leave 9,955 for the answer; 16,000 are needed.
ok a repository that leaves no room for the answer is refused before any request is sent
ok a token provider in place of a key reaches the server as a bearer token, as Entra ID sign-in to Foundry needsWith the layout above, a second question about the same 23,327-token repository is billed for 23,296 cached tokens and costs about a fifth of the first. Put one sentence that changes, such as the date, in front of the files and the cached count is zero. That is the most common way to lose the discount, and it is invisible unless cached_tokens is logged.
The stand-in is a model of the published rules. The tests show that the client builds requests the way those rules reward and reads the usage fields correctly. They do not show how often the real service returns a cache hit, which also depends on traffic and routing. Log cached_tokens from the first day and treat the cost table below as the best case.
What a session costs
With the prices and the caching rules, the cost of a working session is arithmetic. A session here is one repository and a number of questions, each with a 500-token question and 4,000 tokens of reasoning and answer.
def session_cost(prices: Prices, prefix_tokens: int, question_tokens: int, output_tokens: int, questions: int) -> SessionCost:
    """A session is the same prefix sent with each of several questions. The first request fills the cache;
    the rest are assumed to arrive while it is still warm, which is the best case."""
    each_input = prefix_tokens + question_tokens
    cold = prices.cost(each_input, 0, output_tokens)
    warm = prices.cost(each_input, cacheable(prefix_tokens), output_tokens)
    return SessionCost(questions, cold * questions, cold + warm * (questions - 1))
400,000 input tokens, none cached $0.70
400,000 input tokens, all cached $0.07
16,000 output tokens $0.22
ok a full window of input is $0.70, and $0.07 when all of it is cached
ok cached input is one tenth of the input price
ok the cacheable part of a prefix is 0 below 1,024 tokens and moves in steps of 128 above it
ok a 250,000-token repository and a 500-token question leave 149,500 tokens for reasoning and the answer
repository questions no caching cache warm saving
50,000 1 0.14$ 0.14$ 0%
50,000 10 1.44$ 0.74$ 49%
50,000 40 5.78$ 2.71$ 53%
150,000 1 0.32$ 0.32$ 0%
150,000 10 3.19$ 1.07$ 67%
150,000 40 12.78$ 3.57$ 72%
250,000 1 0.49$ 0.49$ 0%
250,000 10 4.94$ 1.40$ 72%
250,000 40 19.77$ 4.42$ 78%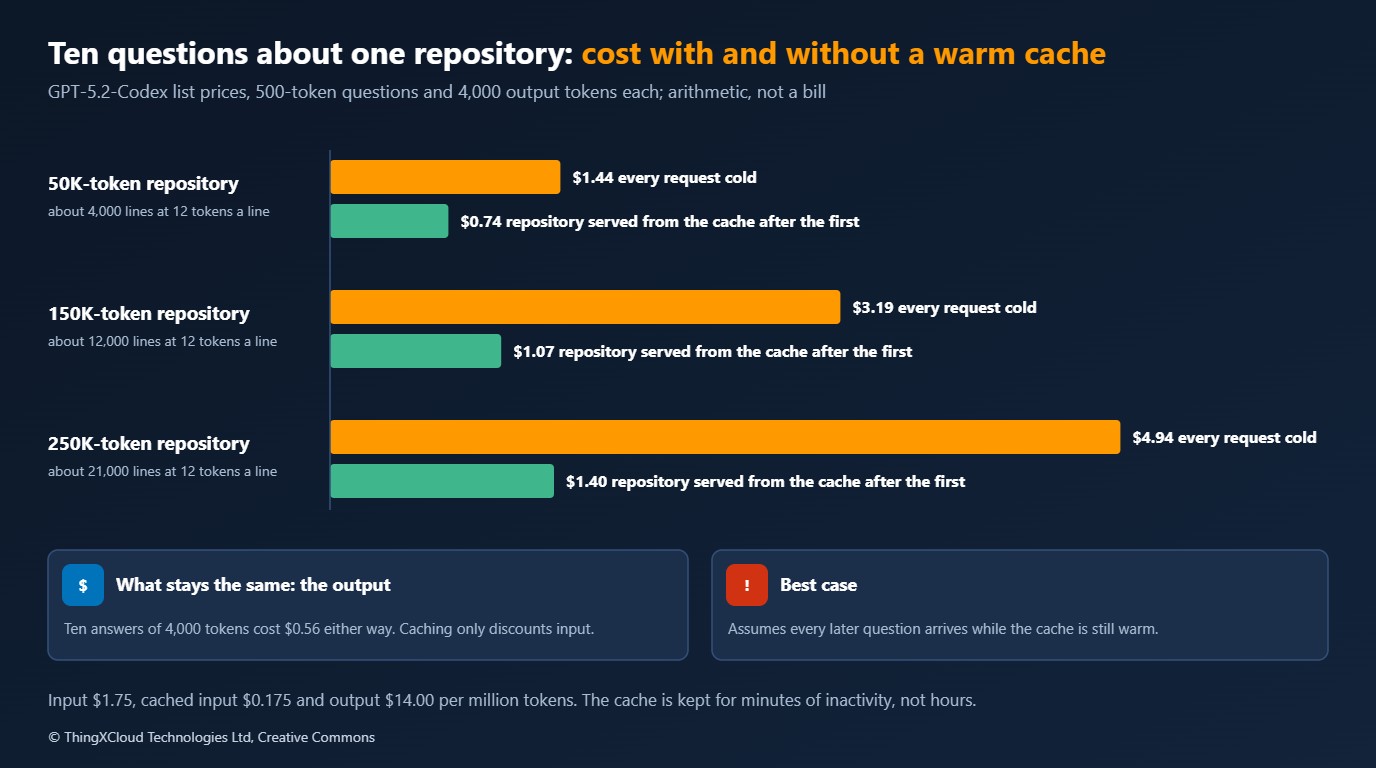
A full window of input costs $0.70, and $0.07 when all of it is cached. Ten questions about a 250,000-token repository cost $4.94 if every request is cold and $1.40 if the repository is served from the cache after the first. The saving is 72%, not 90%, because output is not discounted and at $14 per million it is a large part of each request. Reasoning effort is therefore the other cost control: a higher setting spends more output tokens on every question.
Image input
The model accepts images, and OpenAI describes better reading of screenshots, diagrams and UI surfaces. In the Responses API an image is a content part beside the text. It belongs with the question, after the repository, so that it does not disturb the cached prefix.
        last: list[dict] = [{"type": "input_text", "text": question}]
        if image is not None:
            kind = mimetypes.guess_type(image.name)[0] or "image/png"
            encoded = base64.b64encode(image.read_bytes()).decode("ascii")
            last.append({"type": "input_image", "image_url": f"data:{kind};base64,{encoded}"})
Images are billed as input tokens, and the count depends on size and detail. Whether the model turns your diagrams into code you would merge is a question about quality, which the vendors’ pages illustrate with examples and do not quantify. Test it on your own design files before building a workflow on it, and treat the output as a draft for review.
Calling it through Microsoft Foundry
Azure OpenAI now has a v1 endpoint that the standard OpenAI client can call directly, with no api-version parameter. The model name in a request is the name of your deployment.
def foundry_client(resource: str, api_key_or_token_provider) -> OpenAI:
    """Azure OpenAI in Microsoft Foundry, v1 endpoint. Pass a key, or a token provider from azure.identity
    (get_bearer_token_provider(DefaultAzureCredential(), "https://ai.azure.com/.default")) to use Entra ID.
    The model argument of the session is then the name of your deployment."""
    return OpenAI(base_url=f"https://{resource}.openai.azure.com/openai/v1/", api_key=api_key_or_token_provider, max_retries=4, timeout=600)
The second argument is either an API key or a token provider. For Entra ID, pass the provider from azure.identity named in the comment; the caller needs the Cognitive Services OpenAI User role on the resource. The test above confirms that the client accepts a provider in place of a key and sends its value as a bearer token. Prefer this to keys: there is no secret to store or rotate, and access is granted and revoked in one place.
The Codex CLI can use the same deployment. Microsoft documents a provider entry in its configuration file:
model = "gpt-5.2-codex"            # the name of your deployment
model_provider = "azure"
model_reasoning_effort = "medium"

[model_providers.azure]
name = "Azure OpenAI"
base_url = "https://YOUR_RESOURCE_NAME.openai.azure.com/openai/v1"
env_key = "AZURE_OPENAI_API_KEY"   # the name of an environment variable, never the key itself
wire_api = "responses"
That file is adapted from Microsoft’s documentation and was not exercised here. Before choosing a deployment type, check in the Foundry model catalogue which regions offer the model and where each type processes data; a global deployment and a data-zone deployment give different answers to a data-residency question.
Security and governance
| Concern | What to decide |
|---|---|
| What leaves the boundary | A request with a repository in it sends your source code to the endpoint. Decide which repositories may be sent and to which route. Through Foundry it stays under your Azure agreement and controls |
| Secrets in the repository | Scan before sending. A key committed years ago is still in the files, and now in a prompt |
| Stored responses | The client sets store=False. Confirm your organisation’s data-retention settings with the provider as well |
| Prompt cache | Not shared across organisations or Azure subscriptions. It is still a copy of your prompt held for minutes; include it in your data-handling description |
| Instructions hidden in code | A comment or a README in the repository is input to the model. An agent with tools can be steered by it. Give tools the narrowest permissions and review what the agent proposes |
| Generated code | Untrusted until reviewed, tested and scanned like any other contribution. Keep the same pull-request gates |
| Security capability | OpenAI describes this as its strongest model for cybersecurity work so far, with added safeguards and an invite-only programme for vetted defenders. Some security-related requests may be declined |
| Copilot | The model is off for Business and Enterprise until an administrator enables it. Decide that as policy, not by default |
| Audit | Log who asked, which repository snapshot, token counts including cached tokens, and cost. The cache key in the sample identifies the snapshot |
| Regulated code and data | If test fixtures contain personal or clinical data, the prompt does too. Exclude them or use synthetic fixtures |
Decision framework
| Situation | Choose | Reason |
|---|---|---|
| Developers want the model in the editor | GitHub Copilot or the Codex products | No harness to build. Governance is a policy switch |
| A pipeline step or internal tool, Azure estate | Responses API through Foundry with Entra ID | Tenant controls, no keys, one bill |
| The same, no Azure requirement | Responses API on api.openai.com | Fewest moving parts |
| Many questions about a repository under about 250,000 tokens | Send the files in full, stable prefix first | Simple, and cached input is a tenth of the price |
| A repository that does not fit, or long multi-step work | An agent that reads files on demand, as the Codex harness does | The window is a budget; compaction and retrieval spend it better |
| Occasional single questions | Send only the relevant files | The cache will be cold; pay for less input |
| A decision that depends on answer quality | Run your own evaluation on your own code | The published benchmarks are OpenAI’s, on other tasks |
Key takeaways
- The published facts are a 400,000-token window, 128,000 tokens of output, text and image input, and $1.75, $0.175 and $14.00 per million tokens for input, cached input and output. OpenAI reports results on SWE-Bench Pro and Terminal-Bench 2.0. No vendor source gives a HumanEval score or a latency figure.
- Measured on 310 files of C#, Python and Terraform, application code runs at about twelve tokens a line, so the window holds roughly 33,000 lines, less whatever is reserved for reasoning and the answer.
- Prompt caching needs no flag. It needs a prompt whose beginning does not change: instructions, then the files in a fixed order, then the question and any image.
- A full window of input is $0.70, or $0.07 cached. Ten questions about a 250,000-token repository are $4.94 cold and $1.40 with a warm cache; output is not discounted, so reasoning effort is the other lever.
- Through Microsoft Foundry the same API is reached with the standard client and an Entra ID token provider. Decide which repositories may be sent, scan them for secrets, and log cached tokens and cost per request.
If you are logging cached_tokens for this model in production, I would like to hear what hit rate you see and how it varies with traffic. Leave a comment.
The facts in the first table were read from the OpenAI model page and announcement, the Microsoft Foundry announcement and the GitHub changelog, each linked beside the figure. The code ran in GitHub Actions on Python 3.13 with openai 2.16.0 and tiktoken 0.12.0, installed as those packages stood on 1 February 2026. All 16 checks passed: the token count is repeatable, the cost arithmetic matches hand calculation, and the client, driven through the official package against the local stand-in, survives a 429, places the repository before the question, reads cached tokens, keeps an image out of the cached prefix, refuses a request that cannot fit, and sends a token provider’s value as a bearer token. Not run: any request to GPT-5.2-Codex on either endpoint, so nothing here measures answer quality, real cache hit rates, latency or image token counts; the Codex CLI configuration; and Entra ID sign-in against a real tenant. Prices are list prices, not a bill. The run is here.
The cost model, the session client, the stand-in server and the checks are in gpt52-codex-context-budget in the samples repository. ./ci.sh out runs everything with Python and no account; point count_repository at your own repository to see how much of it fits.
Glossary
- Token— The unit a model reads and writes: a word, part of a word or a symbol. Prices and limits are stated in tokens.
- Context window— The most tokens one request can involve, counting what is sent and what comes back.
- Reasoning tokens— Tokens the model spends working before it answers. They are not shown, they use the window, and they are billed as output.
- Reasoning effort— A request setting, from low to xhigh for this model, that controls how much reasoning is spent.
- Prompt caching— Reuse by the provider of the processed beginning of a prompt that it has seen recently, billed at a lower rate.
- Prefix— The beginning of a prompt. Caching matches on it, so content that changes must come after content that does not.
- Responses API— OpenAI’s current API for model requests, also offered by Azure OpenAI through its v1 endpoint.
- Context compaction— Summarising earlier parts of a long session so that work can continue within the window.
- Microsoft Foundry— Microsoft’s platform for deploying and governing models in Azure, formerly Azure AI Foundry.
- Deployment— In Azure OpenAI, a named instance of a model in your resource. Requests use the deployment name as the model.
- SWE-Bench Pro, Terminal-Bench 2.0— Benchmarks of software-engineering tasks in real repositories and of agent work in a terminal.
References & Further Reading
- → Introducing GPT-5.2-Codex— OpenAI, 18 December 2025: capabilities, benchmarks named, safeguards, availability
- → GPT-5.2-Codex model page— OpenAI: context window, output limit, modalities, prices, features
- → Prompt caching— OpenAI: how the prefix match works and how to structure prompts
- → Responses API reference— OpenAI: request and response shapes, including usage
- → Announcing GPT-5.2-Codex in Microsoft Foundry— Microsoft, 14 January 2026: general availability and prices
- → Prompt caching in Azure OpenAI— Microsoft: the same rules, and what is not shared between subscriptions
- → Azure OpenAI v1 API— Microsoft: the endpoint, the standard client, keys and Entra ID
- → Codex with Azure OpenAI in Microsoft Foundry— Microsoft: configuring the Codex CLI and IDE extension
- → GPT-5.2-Codex is now generally available in GitHub Copilot— GitHub, 14 January 2026: plans, surfaces and the administrator policy
- → tiktoken— The tokenizer used for the counts
- → Sample code for this article— Cost model, client, stand-in server and checks
Discover more from C4: Container, Code, Cloud & Context
Subscribe to get the latest posts sent to your email.