
On this page
Two months after OpenAI’s first DevDay on 6 November 2023, teams building on the OpenAI API have three realistic choices for text work: GPT-3.5 Turbo, the original GPT-4, and the GPT-4 Turbo preview. They differ by an order of magnitude in price, by a factor of sixteen in context length, and in how far their training data reaches. Picking one by reputation leads either to paying GPT-4 prices for work GPT-3.5 Turbo would do, or to discovering in production that the cheaper model cannot follow the instructions.
This article sets out what each model offers as of January 2024, what the DevDay releases changed for developers, how to compare cost for a real workload, and how to test the models against your own prompts. The sample code holds the model data and runs the same prompts through several models with reproducible settings.
The models
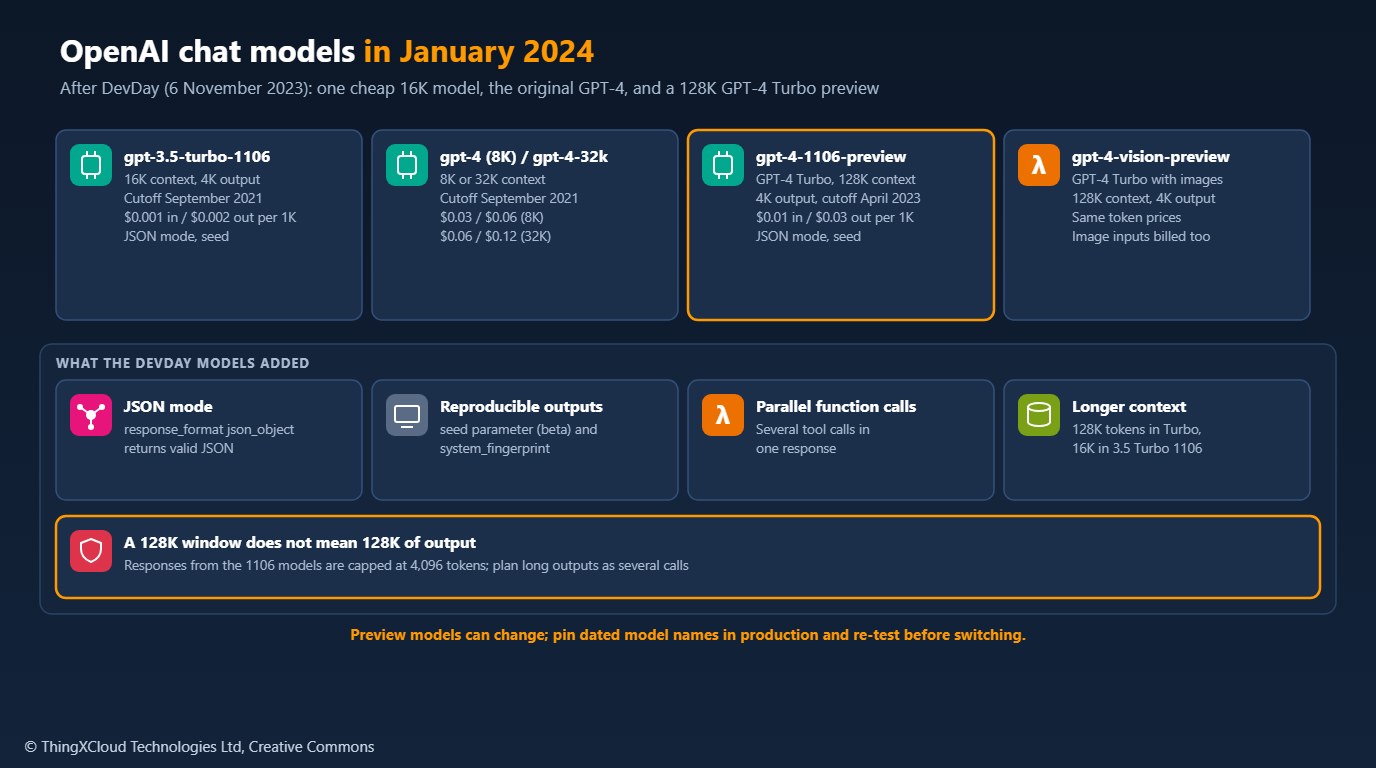
GPT-4 Turbo (gpt-4-1106-preview) was the headline of DevDay. OpenAI described it as offering a 128K context window and knowledge of world events up to April 2023, with input at $0.01 per 1K tokens and output at $0.03, which OpenAI put at 3x and 2x cheaper than GPT-4. It is still a preview: rate limits are lower, and OpenAI has said it may change before a stable release. Its responses are capped at 4,096 tokens however long the input.
GPT-4 (gpt-4, 8K context, and gpt-4-32k) is the original model, with a September 2021 cutoff. At $0.03 and $0.06 per 1K tokens for the 8K version it is the most expensive option, and its main remaining reason is stability for applications validated against it.
GPT-3.5 Turbo was updated at DevDay as well. The new gpt-3.5-turbo-1106 supports 16K context by default at $0.001 per 1K input tokens and $0.002 per 1K output. It is the default for high-volume, well-defined tasks such as classification, extraction from short text and routing.
What DevDay changed for developers
- JSON mode. Setting
response_formatto{"type": "json_object"}on the 1106 models makes the model return valid JSON. The instructions must still mention JSON, and valid JSON is not the same as JSON matching your schema, so validate it. - Reproducible outputs. A
seedparameter (in beta) makes repeated requests return mostly the same output, and each response carries asystem_fingerprintthat changes when OpenAI changes the serving configuration. Together they make evaluations repeatable. - Parallel function calling. A single response can contain several tool calls, cutting round trips for agents that look up several things at once.
- Longer context. 128K tokens in GPT-4 Turbo and 16K in GPT-3.5 Turbo 1106, which changes what can be sent whole rather than chunked.
DevDay also introduced the Assistants API, which manages conversation threads, retrieval and code execution on OpenAI’s side. It is a different way of building, with different trade-offs, and is outside the scope of this comparison.
Compare the cost of a workload
Price per token only matters multiplied by your traffic. A request with 2,000 input tokens and 500 output tokens costs $0.003 on GPT-3.5 Turbo 1106, $0.035 on GPT-4 Turbo and $0.09 on GPT-4 8K. At 100,000 requests a month that is about $300, $3,500 and $9,000. The sample’s model table does this arithmetic, checks that a request fits both the context window and the output cap, and picks the cheapest model that fits:
"""OpenAI chat models as of January 2024, and the arithmetic for choosing one.

Prices are USD per 1,000 tokens from OpenAI's pricing page at the time;
check the current page before relying on them. `max_output` is the most
tokens a single response may contain, which for the 1106 models is far
smaller than the context window.
"""
from __future__ import annotations

from dataclasses import dataclass


@dataclass(frozen=True)
class Model:
    name: str
    context: int            # tokens, input and output together
    max_output: int         # tokens per response
    cutoff: str             # training data cutoff
    input_per_1k: float
    output_per_1k: float
    json_mode: bool         # response_format={"type": "json_object"}
    vision: bool = False


MODELS = {m.name: m for m in [
    Model("gpt-3.5-turbo-1106", 16_385, 4_096, "2021-09", 0.0010, 0.0020, json_mode=True),
    Model("gpt-4", 8_192, 8_192, "2021-09", 0.03, 0.06, json_mode=False),
    Model("gpt-4-32k", 32_768, 32_768, "2021-09", 0.06, 0.12, json_mode=False),
    Model("gpt-4-1106-preview", 128_000, 4_096, "2023-04", 0.01, 0.03, json_mode=True),
    Model("gpt-4-vision-preview", 128_000, 4_096, "2023-04", 0.01, 0.03, json_mode=False, vision=True),
]}


def cost(model: str, input_tokens: int, output_tokens: int) -> float:
    m = MODELS[model]
    return input_tokens / 1000 * m.input_per_1k + output_tokens / 1000 * m.output_per_1k


def fits(model: str, input_tokens: int, max_output: int) -> bool:
    m = MODELS[model]
    return max_output <= m.max_output and input_tokens + max_output <= m.context


def monthly_cost(model: str, requests: int, input_tokens: int, output_tokens: int) -> float:
    return round(cost(model, input_tokens, output_tokens) * requests, 2)


def cheapest_that_fits(candidates: list[str], input_tokens: int, max_output: int,
                       need_json: bool = False) -> str | None:
    ok = [c for c in candidates if fits(c, input_tokens, max_output) and (MODELS[c].json_mode or not need_json)]
    return min(ok, key=lambda c: cost(c, input_tokens, max_output), default=None)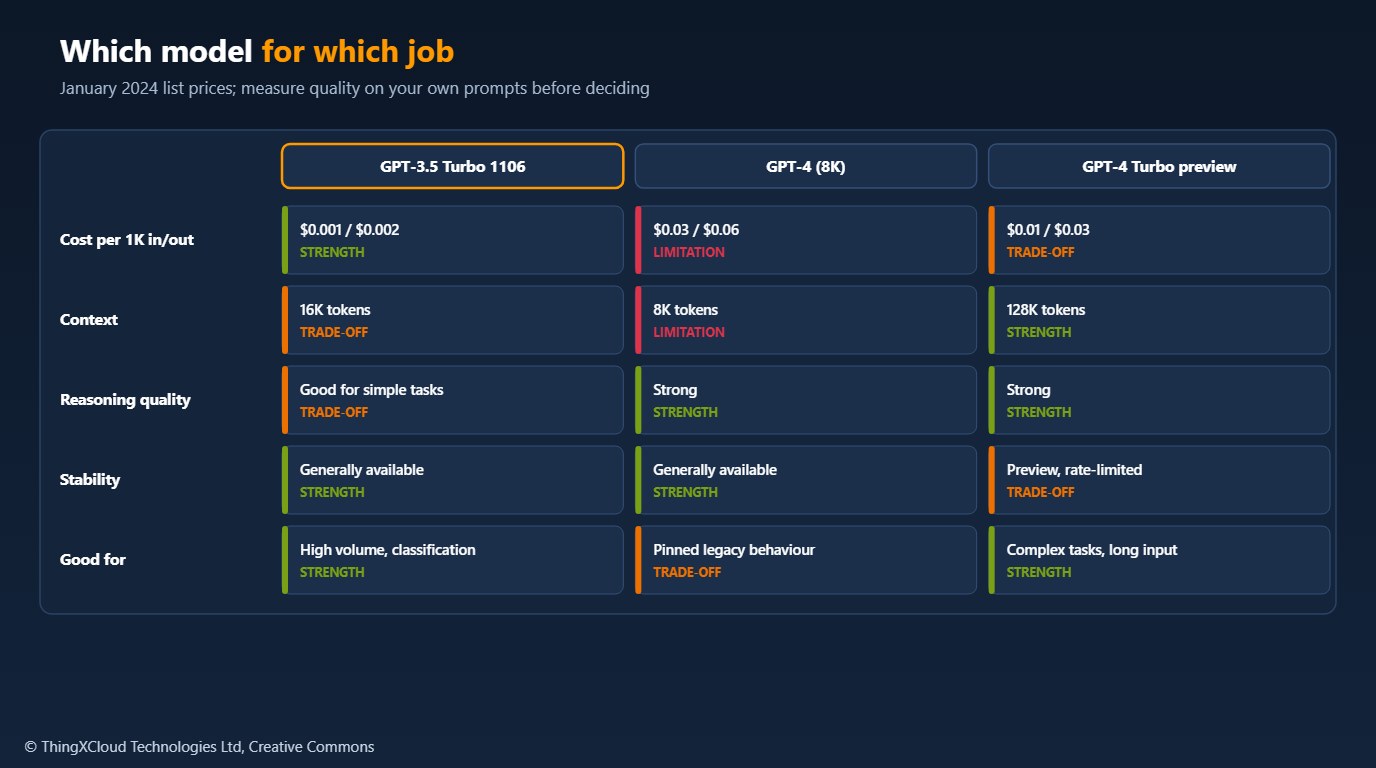
%%{init: {'theme': 'base', 'themeVariables': {'primaryColor': '#FFF3E0', 'primaryTextColor': '#232F3E', 'primaryBorderColor': '#FF9900', 'lineColor': '#232F3E', 'clusterBkg': '#F8FAFC', 'clusterBorder': '#CBD5E1', 'edgeLabelBackground': '#FFFFFF', 'nodeTextColor': '#232F3E'}}}%%
flowchart TD
    A["Collect 50 to 200 real prompts<br/>with expected answers"] --> B["Run GPT-3.5 Turbo 1106,<br/>temperature 0, fixed seed"]
    B --> C{"Meets the quality bar?"}
    C -- "Yes" --> D["Use GPT-3.5 Turbo,<br/>monitor quality"]
    C -- "No" --> E{"Input over 16K tokens<br/>or task needs reasoning?"}
    E -- "Yes" --> F["Run GPT-4 Turbo preview"]
    E -- "No" --> G["Improve the prompt or examples,<br/>then re-test GPT-3.5"]
    G --> B
    F --> H{"Preview limits acceptable?"}
    H -- "Yes" --> I["Use GPT-4 Turbo,<br/>pin the dated name"]
    H -- "No" --> J["Use GPT-4 8K or 32K"]
    classDef aws fill:#FFF3E0,stroke:#FF9900,stroke-width:2px,color:#232F3E
    classDef ok fill:#F0FFF4,stroke:#1D8102,stroke-width:2px,color:#145202
    class A,B,C,E,F,G,H aws
    class D,I,J ok
Test on your own prompts
Benchmarks published by vendors and researchers rank models on general tasks; your task is specific. Collect a set of real prompts with known good answers, run each candidate with temperature 0 and a fixed seed, and compare answers, latency and cost. The sample does that, using JSON mode where the model supports it and checking that JSON answers parse:
"""Run the same prompts through several OpenAI models and compare the results.

Each request uses temperature 0 and a fixed `seed` (a beta feature of the
1106 models that makes outputs mostly reproducible; `system_fingerprint`
changes when the backend does). For JSON tasks, models that support it are
called with JSON mode. The report records answer, latency, tokens, cost and
fingerprint per model so the choice rests on your own prompts.

Usage:
    OPENAI_API_KEY=... python compare.py prompts.jsonl gpt-3.5-turbo-1106 gpt-4-1106-preview
"""
from __future__ import annotations

import json
import sys
import time
from dataclasses import dataclass

from openai import APIError, OpenAI

from models import MODELS, cost


@dataclass
class Result:
    model: str
    prompt_id: str
    answer: str | None
    latency_s: float
    input_tokens: int = 0
    output_tokens: int = 0
    fingerprint: str | None = None
    error: str | None = None

    @property
    def cost(self) -> float:
        return cost(self.model, self.input_tokens, self.output_tokens)


def run_one(client: OpenAI, model: str, prompt: dict, seed: int = 7) -> Result:
    kwargs = {
        "model": model,
        "messages": [{"role": "system", "content": prompt.get("system", "You are a precise assistant.")},
                     {"role": "user", "content": prompt["user"]}],
        "temperature": 0,
        "seed": seed,
        "max_tokens": prompt.get("max_tokens", 500),
    }
    if prompt.get("json") and MODELS[model].json_mode:
        # JSON mode requires the word "JSON" somewhere in the messages
        kwargs["response_format"] = {"type": "json_object"}
    start = time.perf_counter()
    try:
        resp = client.chat.completions.create(**kwargs)
    except APIError as exc:
        return Result(model, prompt["id"], None, time.perf_counter() - start, error=type(exc).__name__)
    elapsed = time.perf_counter() - start
    answer = resp.choices[0].message.content
    if prompt.get("json"):
        try:
            json.loads(answer or "")
        except json.JSONDecodeError:
            return Result(model, prompt["id"], answer, elapsed, resp.usage.prompt_tokens,
                          resp.usage.completion_tokens, resp.system_fingerprint, error="invalid JSON")
    return Result(model, prompt["id"], answer, elapsed, resp.usage.prompt_tokens,
                  resp.usage.completion_tokens, resp.system_fingerprint)


def compare(client: OpenAI, models: list[str], prompts: list[dict]) -> list[Result]:
    unknown = [m for m in models if m not in MODELS]
    if unknown:
        raise ValueError(f"no price data for {unknown}; add them to models.py")
    return [run_one(client, m, p) for p in prompts for m in models]


def main(argv: list[str]) -> int:
    if len(argv) < 2:
        print(__doc__)
        return 2
    with open(argv[0], encoding="utf-8") as fh:
        prompts = [json.loads(line) for line in fh if line.strip()]
    client = OpenAI(max_retries=3, timeout=60)        # retries 429 and 5xx with backoff
    for r in compare(client, argv[1:], prompts):
        print(json.dumps({"model": r.model, "prompt": r.prompt_id, "latency_s": round(r.latency_s, 2),
                          "tokens": [r.input_tokens, r.output_tokens], "cost_usd": round(r.cost, 5),
                          "fingerprint": r.fingerprint, "error": r.error, "answer": r.answer}))
    return 0


if __name__ == "__main__":
    sys.exit(main(sys.argv[1:]))
Record the system_fingerprint with each run. If it changes between two runs, differences in output may come from OpenAI’s side rather than your prompt, and the comparison should be repeated.
GPT-4 Turbo is a preview model with lower rate limits than generally available models. Pin the dated name (gpt-4-1106-preview), keep a fallback model configured, and re-run your evaluation before moving to any new version rather than relying on an alias that OpenAI updates.
Begin with GPT-3.5 Turbo and a well-written prompt with a few examples. Move a task to GPT-4 Turbo only when the evaluation shows GPT-3.5 Turbo misses your quality bar, and consider routing: the cheap model for most requests, the stronger one for those that need it.
By default OpenAI does not use API inputs and outputs to train its models, but data is still processed and retained for a period for abuse monitoring. Check OpenAI’s current data usage terms against your data classification, and keep personal or regulated data out of prompts unless your agreements cover it.
The sample was tested with Python 3.12, openai==1.7.2 (12 January 2024), httpx==0.26.0, pydantic==2.5.3 and pytest==7.4.4: six tests cover cost arithmetic, context and output-cap checks, cheapest-model selection with and without JSON, and the comparison script against a mocked API (seed, temperature, JSON mode only where supported, invalid JSON and API errors). No real API calls were made. Model limits and prices are from OpenAI’s DevDay announcement.
Key takeaways
- As of January 2024: GPT-3.5 Turbo 1106 (16K, cheapest), GPT-4 (8K or 32K, most expensive) and GPT-4 Turbo preview (128K, April 2023 cutoff).
- GPT-4 Turbo costs a third of GPT-4 for input and half for output, but is a preview with lower limits and a 4,096-token output cap.
- JSON mode, the seed parameter and system fingerprints make outputs easier to parse and evaluations repeatable.
- Price a real workload, not a token: the difference between models runs to thousands of dollars a month at modest volume.
- Start with GPT-3.5 Turbo, test on your own prompts, and escalate to GPT-4 Turbo where the evidence says it is needed.
Which model did your evaluation point to, and where did GPT-3.5 Turbo fall short? Share it in the comments.
The complete sample for this article is on GitHub: nithinmohantk/blog-samples-working-repo/gpt-model-compare. Clone it with git clone https://github.com/nithinmohantk/blog-samples-working-repo.git and open the gpt-model-compare folder. Its README says how to run it and what has been verified.
Glossary
- Context window
- The maximum tokens a model handles per request, input and output together.
- Knowledge cutoff
- The date after which the model’s training data has no information.
- JSON mode
- An API setting that makes the model return syntactically valid JSON.
- Seed
- A request parameter that makes sampling repeatable as far as the backend allows.
- System fingerprint
- An identifier of the serving configuration returned with each response.
- Preview model
- A model offered before general availability, with lower limits and possible changes.
References & Further Reading
- → New models and developer products announced at DevDay— OpenAI, 6 November 2023
- → First OpenAI DevDay summarised— OpenAI community summary with prices and limits
- → Sample code for this article— Model table, cost helpers and comparison script
Discover more from C4: Container, Code, Cloud & Context
Subscribe to get the latest posts sent to your email.
